

€ 18,82 Gratis verzending

Gesponsorde links
|
|
18,82 |
Naar shop
|

|
18,82 |
Naar shop
|
|
27,99 |
Naar shop
|
| VERGELIJK ALLE AANBIEDERS (3) | ||
 Beschrijving
Vergelijk aanbieders (3)
Gesponsorde links · Sommige shops betalen ons een vergoeding
€ 18,82 Gratis verzending
€ 18,82 Gratis verzending
€ 27,99 Gratis verzending
Winkels met andere maten
Beschrijving
(1)
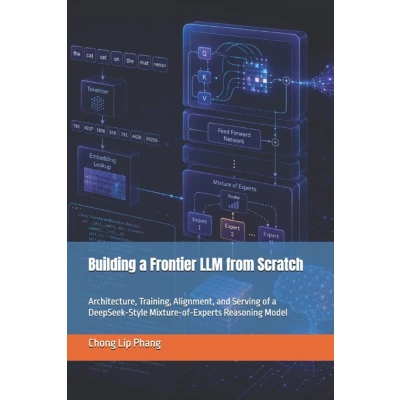
Most "build an LLM" books stop at a small GPT. This one takes you all the way to the frontier.Today's leading models - DeepSeek-V3, GLM, and the reasoning systems behind them - are not just bigger GPTs. They are sparse Mixture-of-Experts networks with Multi-head Latent Attention, trained in FP8 across thousands of GPUs and taught to reason with reinforcement learning. This book builds that entire modern stack from first principles, one component at a time.Starting from tensors and automatic differentiation, you'll implement and understand every layer of a contemporary large language model - tokenization, attention, the transformer block, rotary positions, a decoder-only architecture - and then the techniques that define the frontier: fine-grained Mixture-of-Experts, Multi-head Latent Attention, Multi-Token Prediction, and sparse attention. From there it covers what it actually takes to train, align, and serve such a model at scale.What you'll understand and build: - The full architecture of a modern MoE language model, component by component - Pretraining at scale - FP8 training, distributed and pipeline parallelism, stability, and the systems that keep a run alive - Alignment from SFT and RLHF to DPO and GRPO - the reinforcement-learning recipe behind reasoning models - Inference and serving - KV-cache optimization, paged attention, quantization, continuous batching - The research frontier - reasoning, agents, multimodality, and extreme efficiency - Two full case studies dissecting real frontier models: DeepSeek-V3 and GLM Who it's for: engineers, researchers, and serious students who know some Python and want to understand modern LLMs deeply enough to build one - not just call an API.Every chapter pairs clear explanation with worked examples, illustrative code, and reference tables, and ends with exercises. The result is a single, self-contained path from import torch to a DeepSeek-style Mixture-of-Experts reasoning model.Stop treating large language models as black boxes. Build one.
 Prijshistorie
* Prijshistorie bevat geen data van Amazon, Amazon Marketplace.
Prijzen voor het laatst bijgewerkt op:
 Gerelateerde resultaten
 Productspecificaties


