

€ 34,99 Gratis verzending

Uitgelicht
|
|
34,99 |
Naar shop
|

|
35,22 |
Naar shop
|

|
35,22 |
Naar shop
|
| VERGELIJK ALLE AANBIEDERS (3) | ||
 Beschrijving
Vergelijk aanbieders (3)
€ 34,99 Gratis verzending
€ 35,22 Gratis verzending
€ 35,22 Gratis verzending
Winkels met andere maten
Beschrijving
(1)
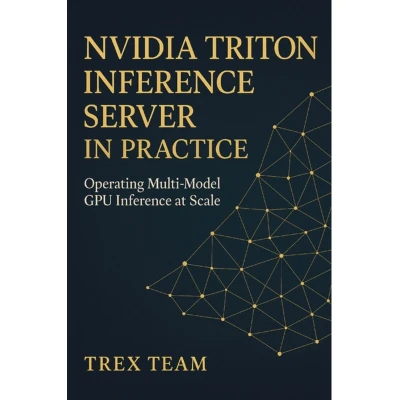
"NVIDIA Triton Inference Server in Practice: Operating Multi¿Model GPU Inference at Scale"NVIDIA Triton is often introduced as a model server, but operating it well in production is a far more demanding discipline. This book is written for experienced machine learning platform engineers, MLOps practitioners, performance specialists, and infrastructure teams who need to run many models efficiently on shared GPU fleets. It treats Triton not as a black box, but as a controllable serving system whose architecture, scheduling, and lifecycle behavior determine real business outcomes.Across the book, readers learn how Triton's request path, model repository, configuration model, and execution instances work together under load. It covers dynamic and sequence batching, queue policy design, multi-model resource governance, server-side pipelines with ensembles and Business Logic Scripting, decoupled and streaming inference, response caching, and rigorous observability and benchmarking. The result is a practical framework for tuning throughput, protecting latency objectives, managing rollouts safely, and making sound backend and version-compatibility decisions.The treatment is intentionally operational and version-aware, emphasizing trade-offs, failure modes, and production control surfaces rather than introductory usage. Readers should already be comfortable with GPU inference, containerized deployment, and modern ML serving concepts. In return, they will gain a systematic, deeply practical understanding of how to design, tune, and evolve Triton deployments that remain fast, st
 Prijshistorie
* Prijshistorie bevat geen data van Amazon, Amazon Marketplace.
Prijzen voor het laatst bijgewerkt op:
 Gerelateerde resultaten
 Productspecificaties


