

€ 34,99 Gratis verzending

Uitgelicht
|
|
34,99 |
Naar shop
|

|
56,85 |
Naar shop
|
| VERGELIJK ALLE AANBIEDERS (2) | ||
 Beschrijving
Vergelijk aanbieders (2)
€ 34,99 Gratis verzending
€ 56,85 € 9,99 verzendkosten Totaal € 66,84
Winkels met andere maten
Beschrijving
(1)
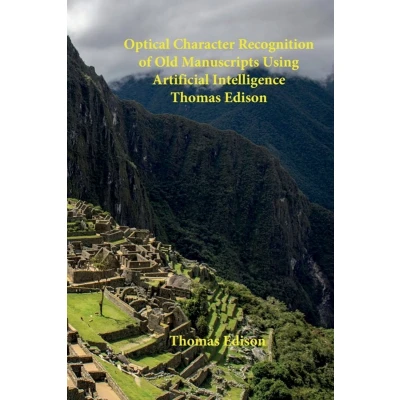
Optical Character Recognition of Old Manuscripts Using Artificial Intelligence delivers a comprehensive computational treatment of automated text extraction, document image restoration, and pattern recognition for historical and degraded codices. As cultural heritage institutions digitize physical archives, processing historical manuscripts presents severe technical obstacles, including non-standard typography, ink bleed-through, parchment distortion, and variable layout structures. This monograph establishes the theoretical foundations, algorithmic pipelines, and neural network architectures required to convert complex historical script images into machine-readable digital text.The volume details preprocessing methodologies, non-linear noise reduction, layout analysis, line segmentation algorithms, and multi-scale feature extraction tailored to historical artifacts. It examines optical character recognition frameworks utilizing convolutional neural networks, recurrent neural architectures, transformer models, and vision-language integration. Designed for computer vision engineers, artificial intelligence researchers, document processing specialists, and computational humanities scholars, this text delivers rigorous methodologies to enhance transcription accuracy, automate archive indexing, and preserve historical documents.
 Prijshistorie
* Prijshistorie bevat geen data van Amazon.
Prijzen voor het laatst bijgewerkt op:
 Gerelateerde resultaten
 Productspecificaties


